Merry Christmas


Out at the theatre

Wood is stacked and ready for winter

In preparing for some PsephoAnalytics work on the upcoming provincial election, I’ve been wrangling the Elections Ontario data. As provided, the data is really difficult to work with and we’ll walk through some steps to tidy these data for later analysis. Here’s what the source data looks like: Screenshot of raw Elections Ontario data A few problems with this: The data is scattered across a hundred different Excel files Candidates are in columns with their last name as the header Last names are not unique across all Electoral Districts, so can’t be used as a unique identifier Electoral District names are in a row, followed by a separate row for each poll within the district The party affiliation for each candidate isn’t included in the data So, we have a fair bit of work to do to get to something more useful.
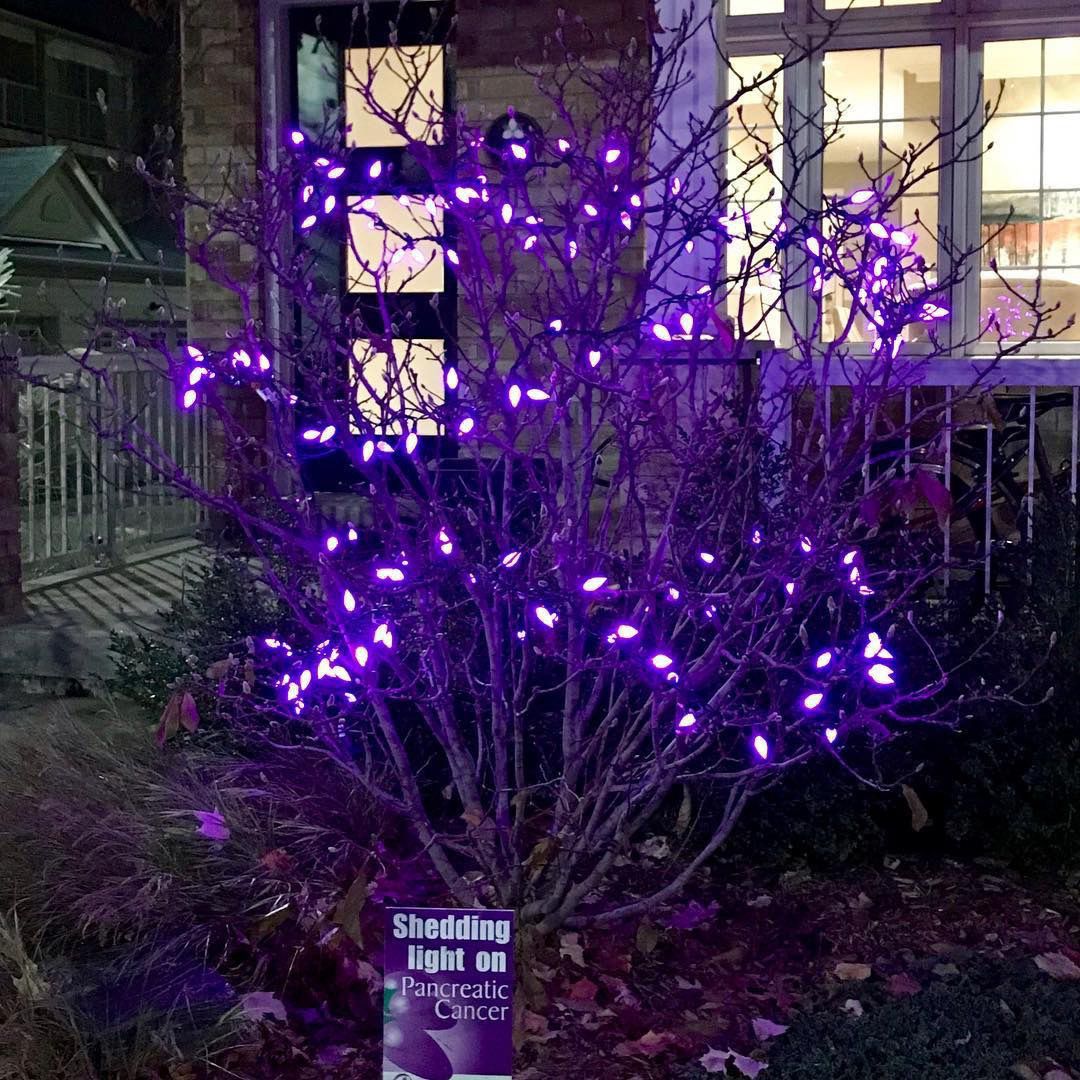
All lit up for #WorldPancreaticCancerDay a whole day in advance
The past few years, I’ve delivered an introduction to using R workshop that relied on manipulating Ministry of Finance demographic projections. Analyzing these data was a great case study for the typical data management process. The data was structured for presentation, rather than analysis. So, there were several header rows, notes at the base of the table, and the data was spread across many worksheets. Sometime recently, the ministry released an update that provides the data in a much better format: one sheet with rows for age and columns for years.
Organizing
Sack of candy
Scarecrow and the ninja